wanile.
Start free trial
Message the founder
Hire LLM engineers

Hire LLM engineers. Features tested like the rest of your code.

Hire generative AI developers who put large language models into products that run every day: extraction, summaries, classification, drafting and chat. Each feature ships with evals, cost tracking and guard rails, reviewed by a senior engineer. They join your team within a week, and the first 7 days are free.

Start your 7-day free trialRead the Go Legal AI case study

What they build. LLM features that hold up.

Calling a model is easy. Making it right often enough, fast enough and cheap enough for real users is the work.

Tools we use
ClaudeGPTGeminiLlamaQwenModel routingLoRA fine-tuningVercel AI SDKLLM-as-judgeCI eval gatesLangfuse
What they cover
Extraction from documents, emails and forms into clean, structured data.
Summaries and briefs from long material, such as reports and board packs.
Classification and routing: tickets, leads, invoices and intents.
Drafting with a person in the loop: replies, documents and journal entries.
Model routing: the cheapest model that passes the evals, a stronger one when it's needed.
Guard rails: structured outputs, personal-data scrubbing, prompt-injection checks and fallbacks.

LLM features in production. With measured results.
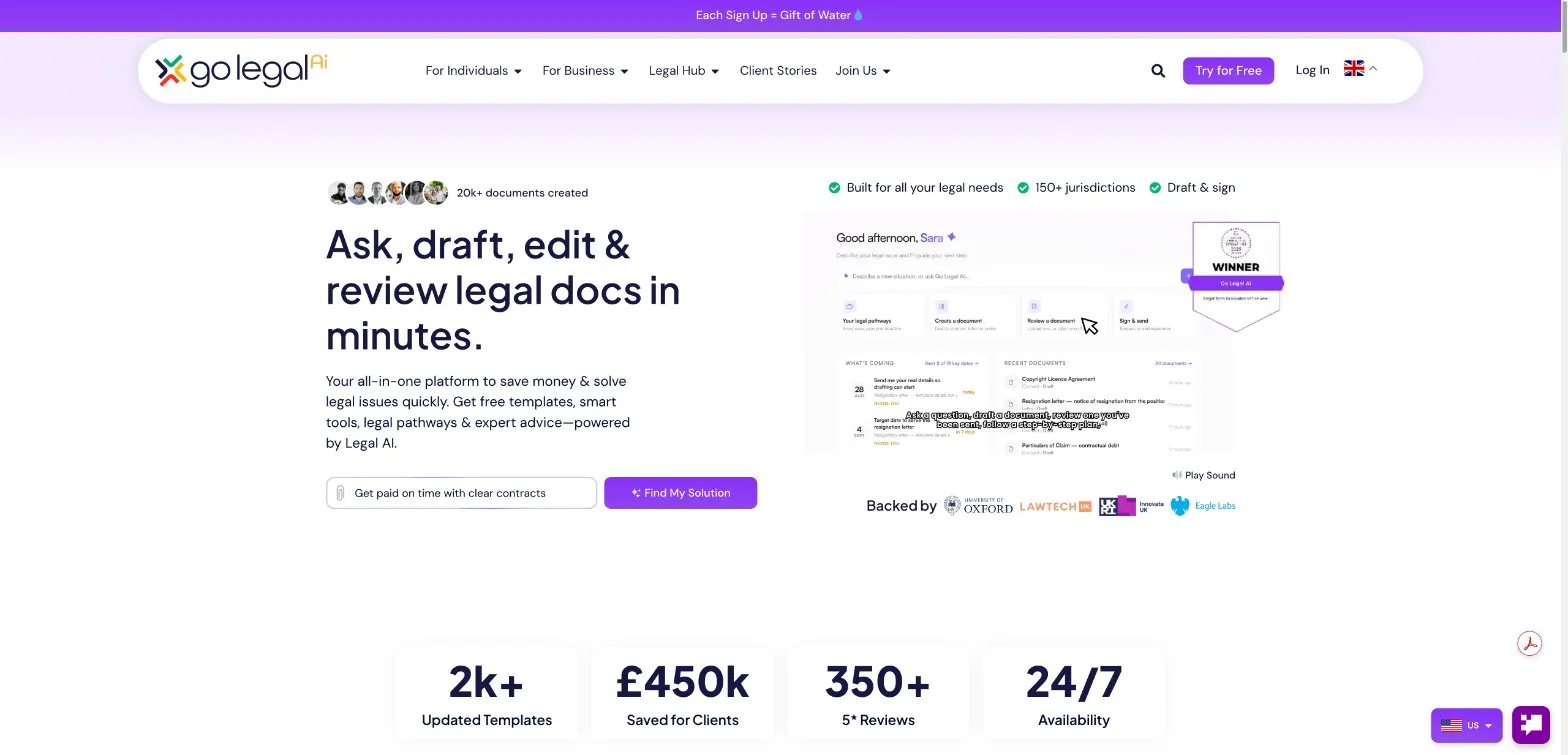
go-legal.ai
Go Legal AI, live product
Go Legal AILegal AI · United Kingdom

A legal AI platform that drafts, reviews and explains documents for UK individuals and small businesses.

Built on the Vercel AI SDK: guided document drafting through short questionnaires, and a multi-agent contract review that flags risky clauses. Designed never to present itself as a lawyer.
Live; full rebuild in progressRead the case study →
talvagt.com
TalVagt, live product
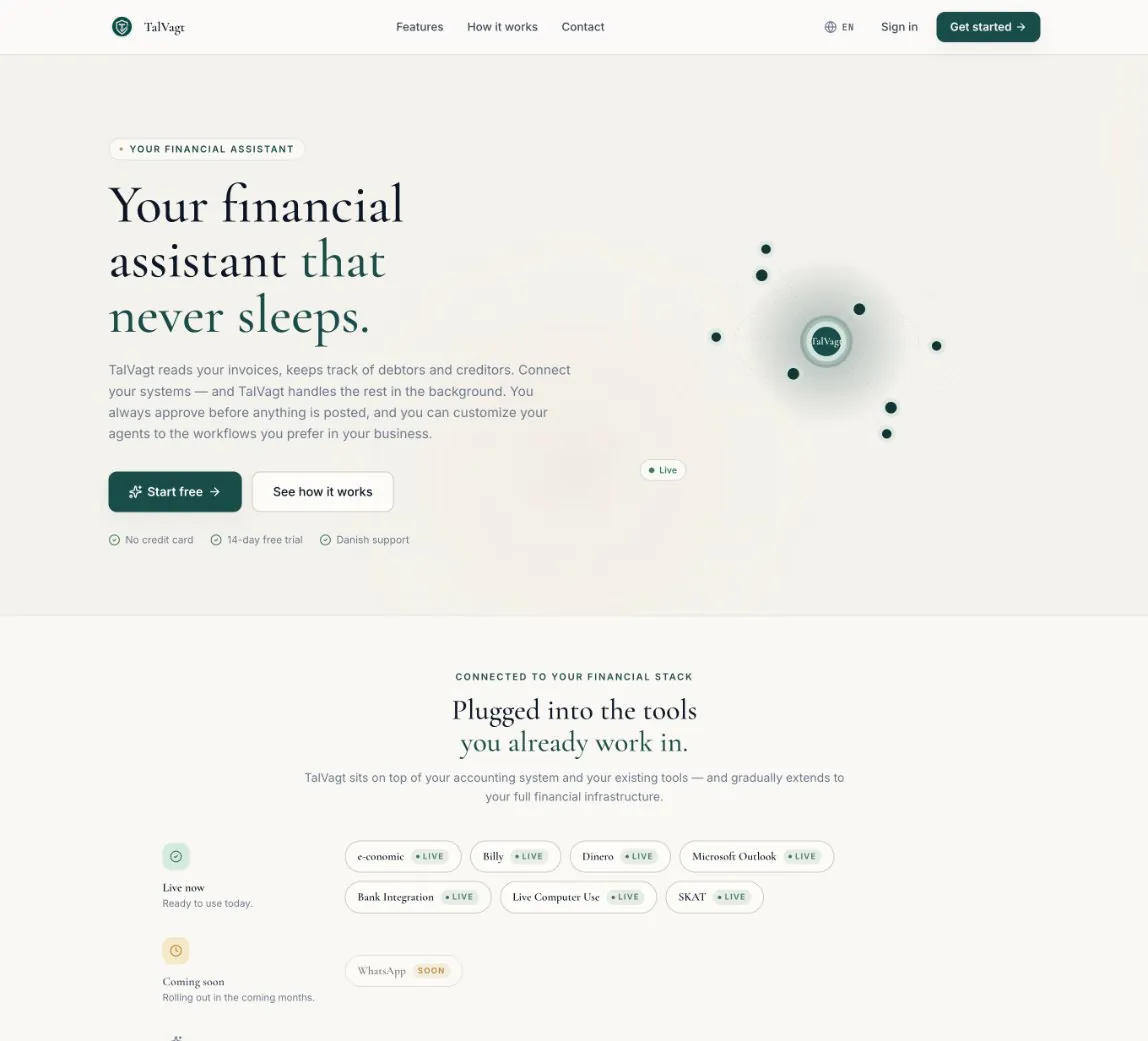
TalVagtAI agents · Fintech · Denmark

An AI bookkeeper that works around the clock for Danish small businesses.

Language models read invoices and draft the journal entries. Personal data is scrubbed before any model call, and memory on pgvector improves each suggestion.

Live, with a 14-day free trialRead the case study →
AI · A European wellness groupDocument intelligenceVision-first extraction of complex PDF reports, cross-checked by a second model. Personal data is removed on a local service before any cloud AI sees it. Tested against a 10-document adversarial set.Proof of concept · client not named

Results BoardLens reported. In their words, on Clutch.

These numbers come from BoardLens's own review on Clutch.

Agentic AI for board directorsBoardLens · Jan to Jun 2025 · 5.0 / 5
< 120 sto analyse a 40-page board pack (P95)
80%+of invited directors ran a report in week one of the private beta
~60%less manual slide review (self-reported, 12 users)
8.9 / 10usability score (10 participants)
$0.60or less in model cost per analysis
0P0 or P1 findings in an external penetration test

How your engineer ships an LLM feature. Evals first.

Define

Decide what good looks like.

Real examples, with the answers you'd accept. That becomes the eval set and the bar the feature must clear.

Compare

Try the models on your data.

Your engineer tests models and prompts against the eval set and notes the quality, speed and cost per call of each.

Harden

Add the guard rails.

Structured outputs, retries and fallbacks, personal-data scrubbing and checks against prompt injection.

Run

Trace it in production.

Every call is logged with its cost. Evals run in CI, so a prompt change can't quietly make things worse.

Your engineer joins your repo and standups, and your lead approves every change. How we work →

Engineers you can hire. Profiles you can check.
Portrait of Arslan Haroon
Arslan HaroonSenior Full-Stack AI Engineer · Tech Lead

Tech lead who has led 10+ AI-driven products, from agentic systems to RAG architectures.

Agentic AI systemsLLM workflowsRAG architecturesSee the full profile →
Portrait of Ali Abyer Nasir
Ali Abyer NasirLead Software Engineer

Leads backend, platform and cloud work: RAG pipelines, LLM integrations and voice-agent workflows.

RAG pipelinesLLM integrationsVoice-agent workflowsSee the full profile →

Questions we get asked.

In practice, very little. Both build products on language models. Ours also write the evals, track the cost and add the guard rails, so the feature holds up with real users.

The cheapest one that passes your evals. Your engineer tests Claude, GPT, Gemini and open-weight models on your own examples, then routes between them by cost and quality.

The engineer measures cost per call from the first prototype, caches what repeats, trims the context and sends easy work to smaller models. You'll know the cost per call before you launch.

Yes, when it's the right tool, usually with LoRA on an open-weight model. Most features don't need it: better retrieval and prompts get there first, for less.

Yes. We work on accounts you control, can strip personal data before any model call, and can run open-weight models on your own infrastructure when data can't leave.

Yes. They start by building an eval set from real traffic, so the problem is measured before anything changes.

More ways to hire

An LLM feature that's stuck?

Tell us what it should do. We'll say honestly what it takes to make it reliable.

Book a free call